Accelerate Data Product Delivery with an Agentic Ingestion Partner

An AI-powered ingestion agent that turns a conversation into production-ready data pipelines — automating source profiling, strategy selection, artefact generation, and validation across every data source, every time.

The Client

A publicly listed global (re)insurance group headquartered in the United States, operating across property, casualty, and specialty lines. The organisation underwrites complex risks for multinational corporations and institutional clients, with a strong presence across North America, Bermuda, Europe, and Asia.

As a large-scale international carrier operating within the Lloyd's market, the company is subject to stringent regulatory and financial reporting requirements. Its global footprint, underwriting complexity, and capital management obligations demand high standards of governance, accuracy, and transparency across regulatory submissions.
$18B+
Gross Written Premiums
3000+
Employees worldwide
100+
Countries of operation
Support Image
Cta Image

The Challenge

The organisation's data engineering teams faced an accelerating backlog of ingestion requests across multiple source systems, external Databricks platforms, SQL databases, and file-based landing areas. Each new data source required days of manual work: profiling schemas, writing SQL templates, configuring pipelines, generating DDLs, registering strategies, and validating results across RAW and CLEAN layers.

With no standardised framework and no automated tooling, pipeline quality depended entirely on individual engineer expertise. Naming conventions drifted, ingestion strategies were inconsistently applied, and testing was often skipped under delivery pressure. The result was a growing estate of fragile, poorly documented pipelines that slowed downstream data product development.

The organisation needed to industrialise ingestion delivery, making it fast, repeatable, and quality-assured regardless of engineer experience level.

Our Solution
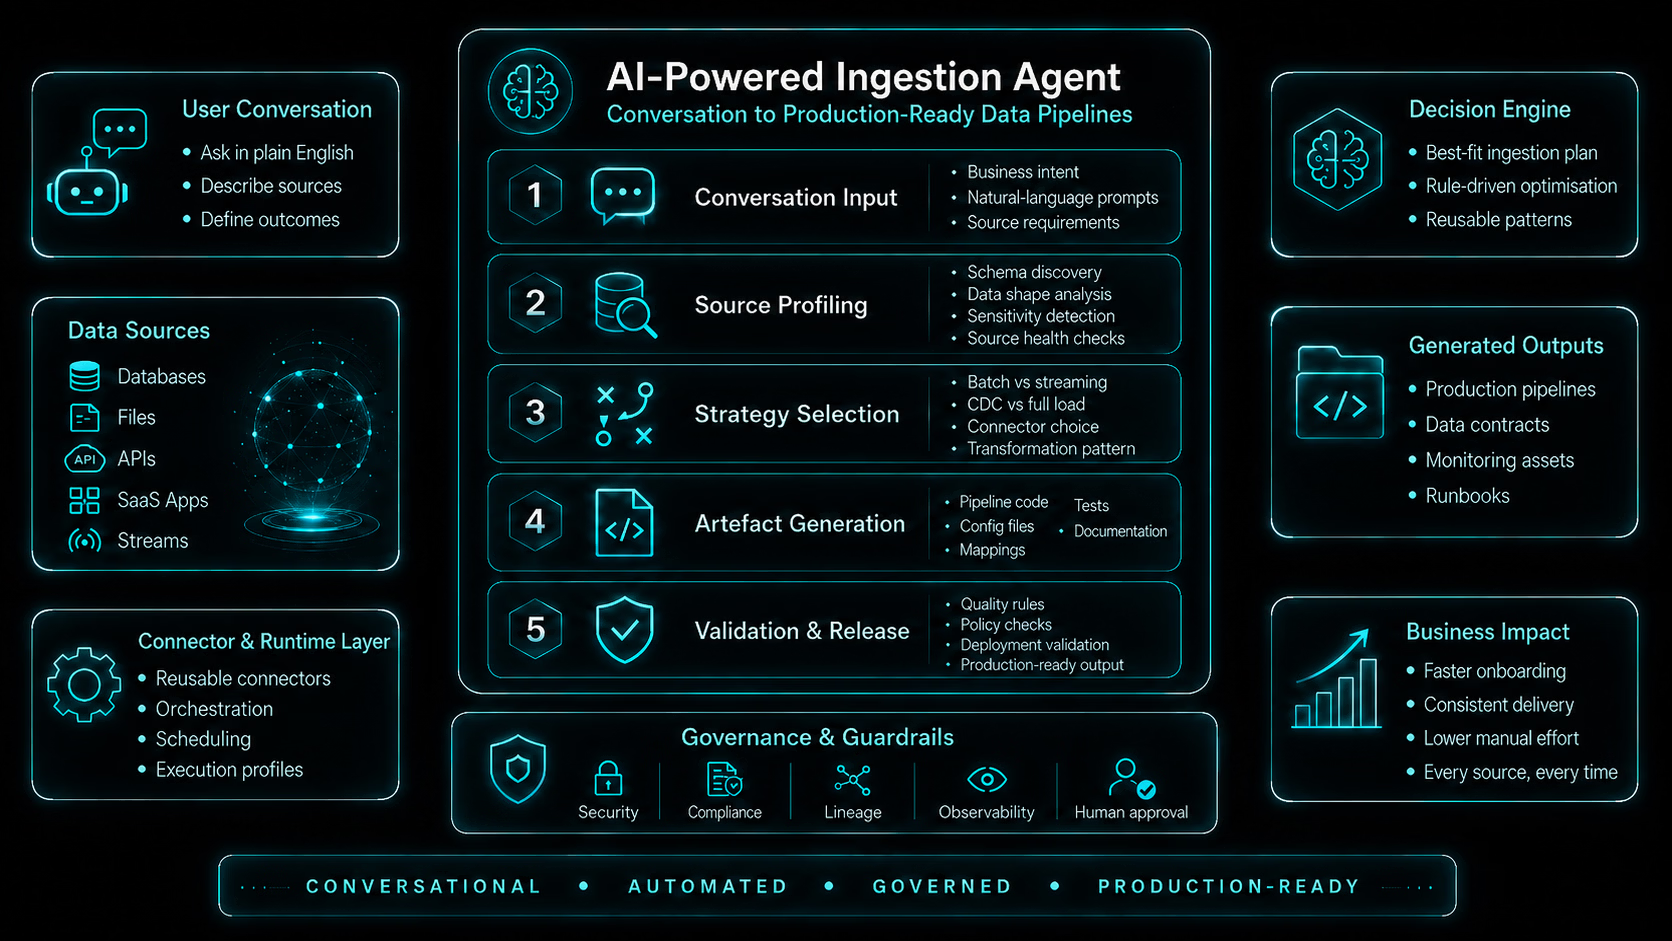
Designed and deployed an agentic ingestion specialist, an AI-powered agent that guides engineers through the complete ingestion workflow via natural language, from source profiling to validated, production-ready code.
Conversational Requirements Capture
Engineers describe the source in plain language. The agent asks targeted questions to determine source type, ingestion mode, partitioning strategy, and cleaning approach — ensuring every required parameter is captured before a single line of code is generated. No specialist knowledge of the underlying platform is required.
Automated Source Profiling & Strategy Recommendation
The agent profiles the source table autonomously — analysing schema, row counts, data size, watermark columns, and change patterns. It classifies the data as Reference, Dimension, or Fact, then recommends the optimal RAW ingestion mode (incremental or full load) and CLEAN layer strategy (SCD Type 2 merge, snapshot history, or complete replacement) with clear, context-aware reasoning.
Zero-Code Artefact Generation
From a confirmed configuration, the agent autonomously generates all 10 required pipeline artefacts: SQL templates, strategy classes, ingest and clean pipelines, RAW and CLEAN DDLs, factory registration, and workflow updates. Zero manual coding is required — the complete ingestion stack is produced in seconds, consistently and to standard.
Human-in-the-Loop Quality Gate
Before any artefacts are generated, the agent presents a complete configuration summary for human review and explicit approval. Engineers verify ingestion mode, partitioning strategy, business keys, and CLEAN layer approach — combining the speed of AI generation with the confidence of expert oversight. No code is produced without a human sign-off.
Automated Two-Run Validation
The agent executes two full ingestion cycles per dataset and validates both using automated tooling — checking row counts, partition structure, SCD column integrity, and strategy-specific behaviour. The first run establishes the baseline; the second confirms the strategy works correctly under real conditions. No code is committed until both runs pass.
Governance & Observability
Every pipeline generated by the agent exposes end-to-end data lineage, quality metrics, and reconciliation summaries through Unity Catalog and Azure Monitor integration. Data product owners and platform teams gain full visibility into the health and trustworthiness of the data estate, supporting auditability and proactive issue detection across all domains.
Agentic AI data ingestion workflow

The Value

The agentic data engineering platform transformed the organisation's ability to deliver trusted data products at scale—cutting ingestion delivery from a full day of manual work to under 10 minutes, with built-in quality controls and domain alignment enforced automatically.
Faster Pipeline Delivery
144x
What took a full day of manual engineering now completes in under 10 minutes. 50 new data sources previously requiring 50 days to onboard are now delivered in a single day.
Reduction in Data Quality Issues
95%
Built-in reconciliation and automated quality gates eliminated 95% of data issues previously discovered by downstream consumers, restoring trust across the data estate.
Engineering Capacity Unlocked
70%
70% of engineering time previously spent on manual pipeline coding was redirected to data product ownership, domain design, and strategic data initiatives.
Natural Language Requirements Interface
The agent guides developers through requirements capture entirely in natural language, asking targeted questions to elicit ingestion strategies, business rules, quality thresholds, and domain context — ensuring nothing is missed before a single line of code is generated.
Zero-Code Delivery with Human-in-the-Loop
Developers define requirements; the agent writes all the code. Every generated pipeline is automatically validated against engineering standards before being surfaced to a human reviewer for final approval, combining the speed of AI generation with the confidence of expert oversight.
Engineers Elevated to Data Product Owners
With the agent handling all pipeline generation, data engineers are freed from manual coding entirely, shifting their role to owning data products, defining domain requirements, and verifying agent output.